Writing.
An archive of whatever I was building, breaking or figuring out at the time, jailbreaks and all.
AI
2026
- A First Look at Jev
A first look at TypeSafe's Jev, the model that answers questions instead of writing. The cheapest paid LLM on OpenRouter matched it on accuracy for a fifth of the price, but Jev's probabilities were the best calibrated as they came, and twenty questions about one document cost a tenth per answer of asking one.
AI 23 Sept - The State of Local AI Image Generation
Four open image models on one RTX 5090 against Nano Banana Pro and GPT Image 2.5, ten everyday prompts, scored blind. Three local models made nine usable images out of ten, and Z-Image Turbo did it in 2.6 seconds each. The newest, Qwen-Image-2.1, made six. Side by side, I still preferred a cloud image for nine prompts in ten.
AI 21 Sept - Qwen3.8-27B vs Opus 4.7 Bakeoff
Qwen's model card puts its 27B above Opus on SWE-bench Pro. At Q4 on one RTX 5090, inside three different coding agents on three scored tasks, the local model matched Opus 4.7's scores and took 1.6 to 2.9 times as long to get there.
AI 11 Sept - MiniMax H3 on One RTX 5090
Measured generation time, memory use and output from MiniMax H3 checkpoints and turbo LoRAs running on a single RTX 5090.
AI 3 Sept - An AI Agent Overclocked My RTX 5090 Overnight
A coding agent tuned an RTX 5090 overnight. A perplexity check caught unstable settings that ordinary benchmarks missed, and the profile it shipped improved decode speed by 4.2%.
AI 28 Aug - Quantising Qwen3.8-27B: Where Quality Plateaus
How five quantisations of Qwen3.8-27B performed on executed coding tests, how their generation speed and context capacity changed, and which precision levels produced a measurable return on one RTX 5090.
AI 27 Aug
2025
- A Throwaway Windows Desktop an AI Agent Can Drive
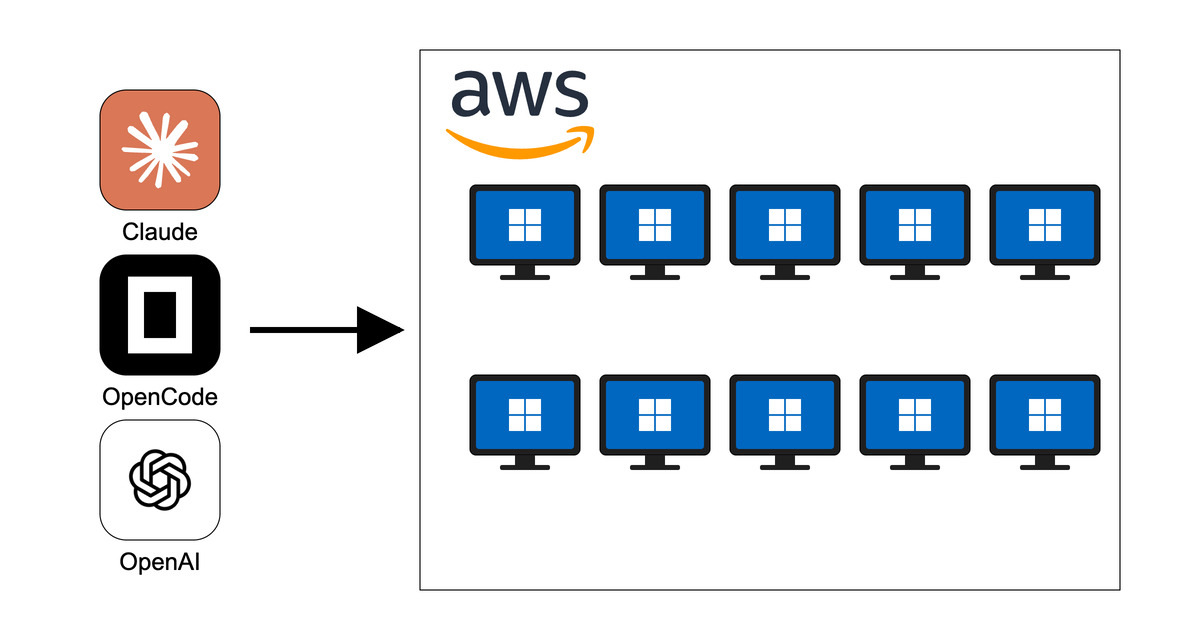
A small provisioning tool turns EC2 instances into disposable Windows GUI workers that AI agents can operate independently, inspect live and destroy after use.
AI 4 Dec - What Is RAG, and Why Can't You Just Give an AI All Your Documents?
A local AI experiment comparing one huge prompt with vector search, keyword search and a small RAG pipeline.
AI 12 Jun - Running a 14.8B Reasoning Model on One RTX 5090
A 29.55 GB reasoning model fit on one desktop GPU and generated at 52 tokens per second. Quantisation made it smaller and faster.
AI 8 Feb